Sources
Which documents, systems and formats? DMS, drives, wiki, email, specialist systems.
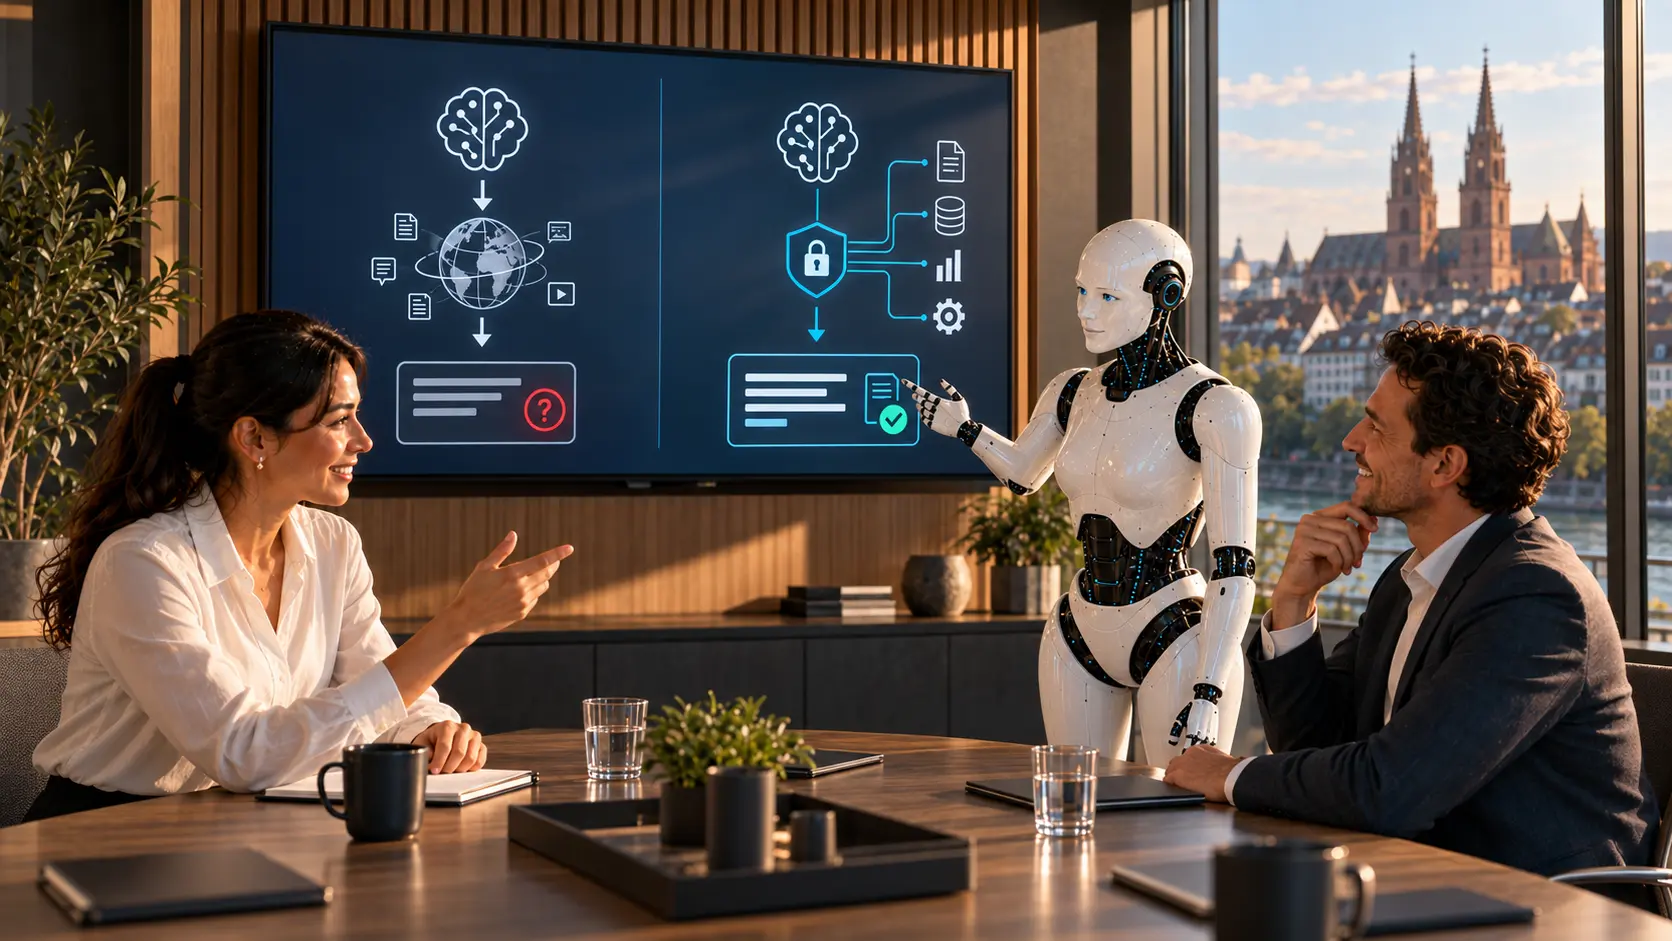
RAG means a system searches approved documents for relevant passages and uses them to draft an answer with sources. Search, permissions and quality must be checked.
In brief: A RAG system searches documents for relevant passages and drafts an answer from them. The answer is meant to cite sources. Quality depends on sources, search, permissions and measurement.
Which documents, systems and formats? DMS, drives, wiki, email, specialist systems.
Split, structure, add metadata and permissions.
Semantic and keyword search across prepared text passages.
Find relevant passages with a permission check for each user.
The model writes the answer from the passages found and is meant to cite them.
Retrieval quality, answer quality, coverage – continuously in Studio.
| Intended support | Limit |
|---|---|
| Prepare answers from existing documents | Reliably fill in missing knowledge |
| Cite sources and respect permissions | Resolve contradictions in the sources on its own |
| Stay up to date when sources are maintained | Recognise outdated documents if nobody flags them |
| Run locally (Private AI) | Deliver good results without preparation |
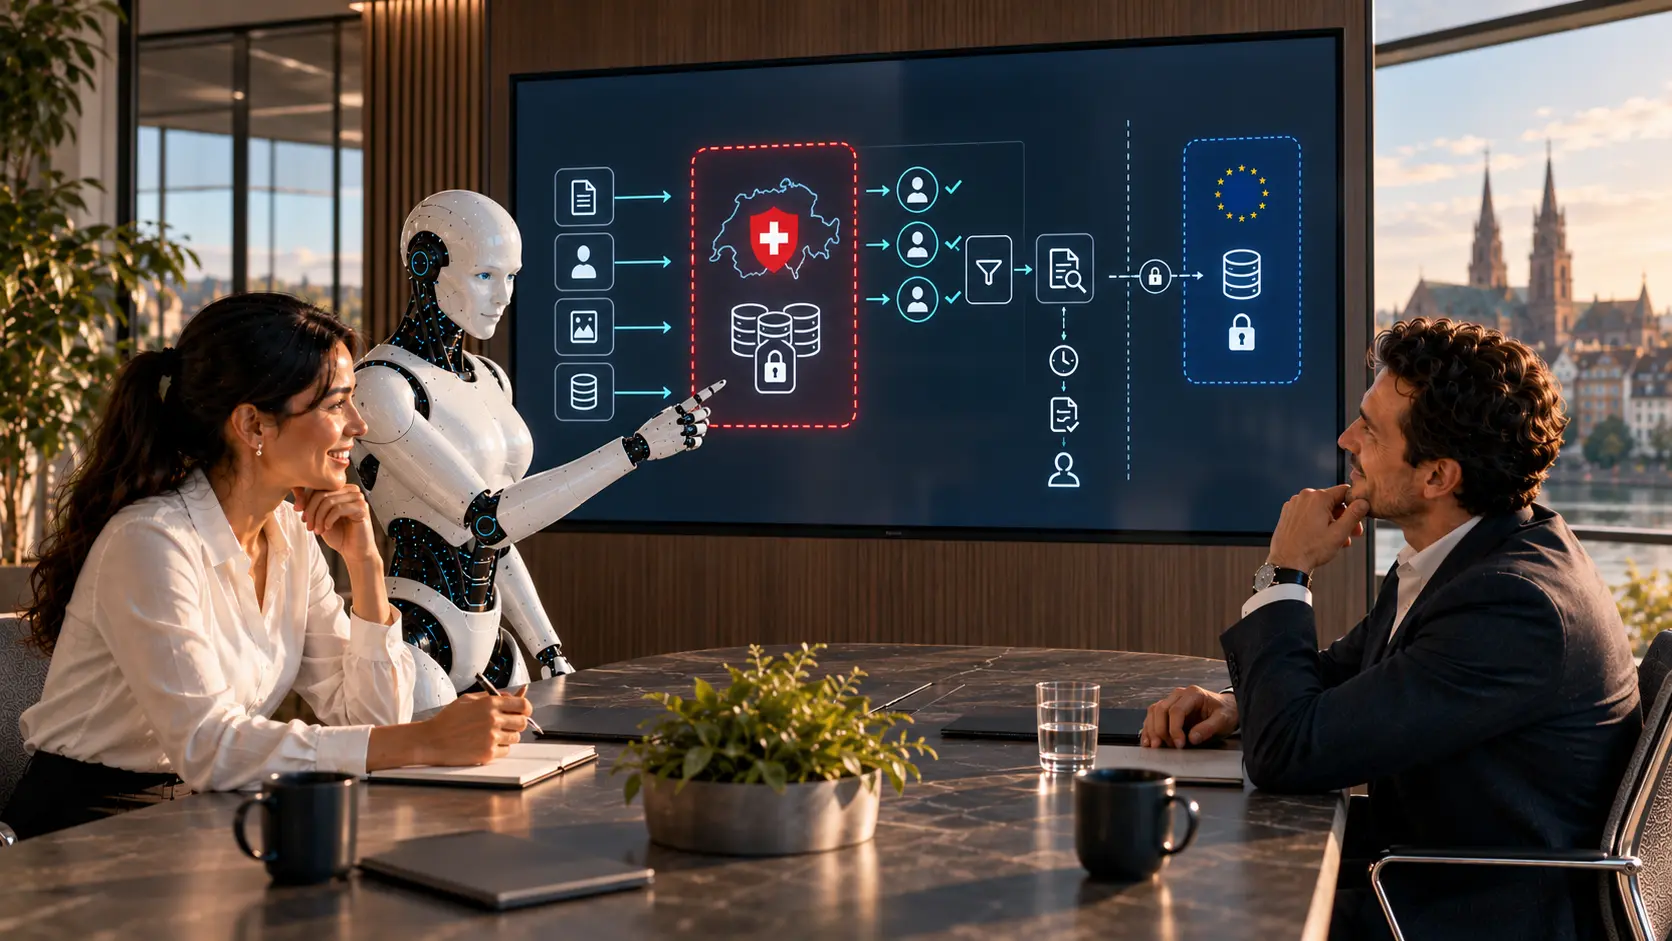
A knowledge system must respect the permissions of its sources. That is why the search is designed to check each user’s rights before a text passage is passed to the model.
This applies to client data at accounting firms just as much as to project documents in construction.
For a test, yes. For live operation, it lacks permissions, up-to-date content, measurement and integration – which is exactly what RAG Engineering covers.
No. RAG accesses the documents at runtime; the model is not trained. Fine-tuning is the exception, not the norm.
Publicly, we show the principle, layers and data flow at a high level. Internal topology, routing rules, security rules and version states stay internal.
We state the maturity of each building block openly. Phrases such as “is designed to” describe the architecture, not a client deployment. Studio, Agents and parts of Factory run in our own development and operating environment and are continuously extended. Further operating models, multiple nodes and private and local installations will follow step by step.
We check sources, permissions and operation for your case.